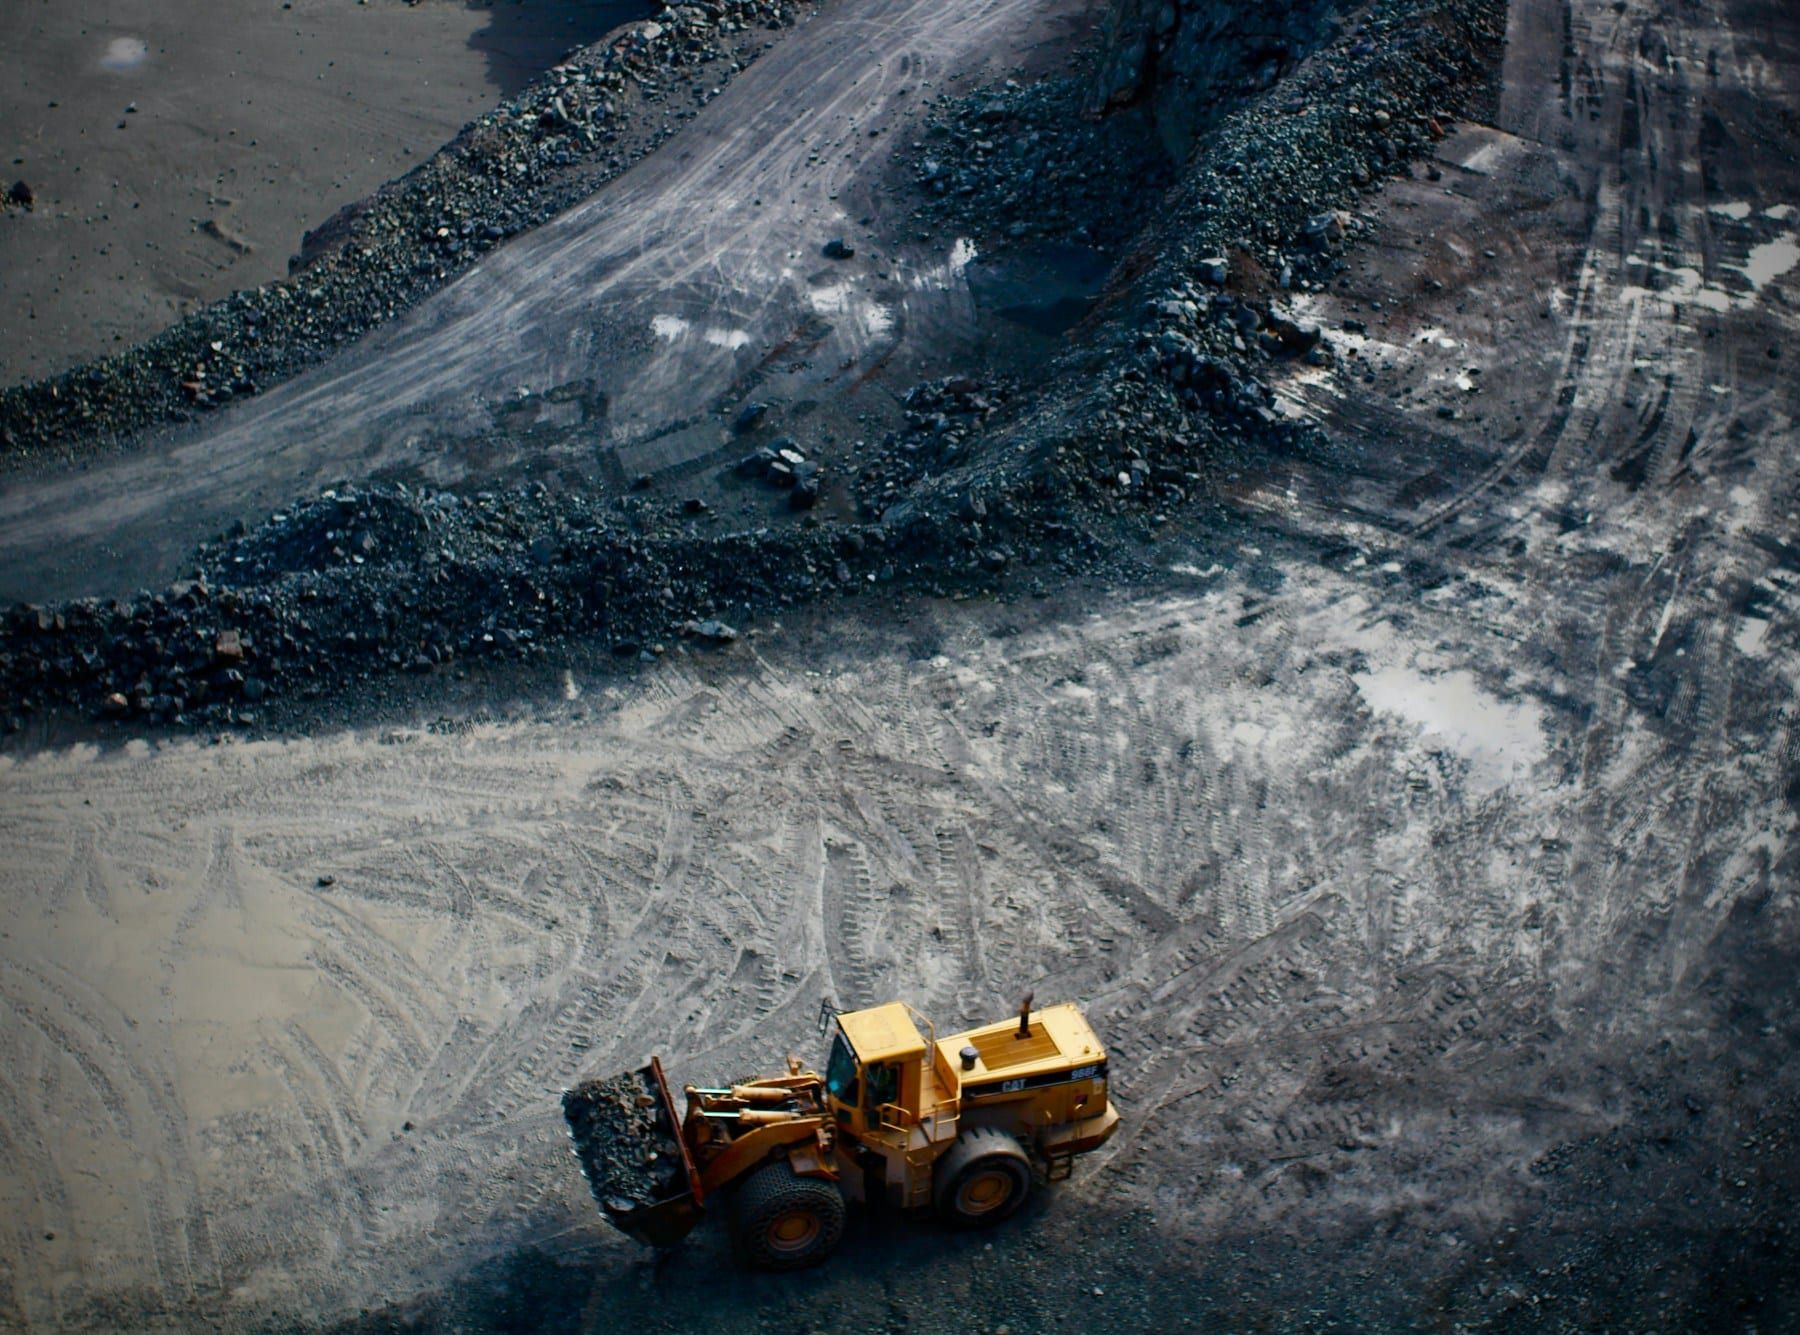
Unplanned failures of haul trucks, conveyors, crushers and pumps are among the most expensive events on a mine site. They stop production, create secondary damage and put people close to equipment that is behaving unpredictably. Predictive maintenance uses data the site already collects to see those failures coming.
Start with the failure, not the algorithm
Every useful model answers a specific question: which of these assets is most likely to fail in the next few weeks, and why? Before any modelling we work with maintenance planners to list the failure modes that matter most, the warning signs technicians already look for, and the decisions a better warning would change. That list decides which data is worth collecting.
The data that matters
Most sites already hold what is needed, spread across several systems:
- Condition data: vibration, temperature, oil analysis and pressure from sensors and handheld surveys.
- Operating data: load, speed, duty cycle and operator events from the fleet or plant control system.
- Maintenance history: work orders, component changes and failure codes from the maintenance system.
The international standard for condition monitoring, ISO 17359, describes the same logic: identify the failure modes, choose measurements that reveal them, set alert criteria, then act and review.
Building and validating models
We align the data by asset and time, then train models to recognise the patterns that preceded past failures. Two checks matter more than model choice:
- Validate on history the model has never seen. If a model cannot flag last year’s failures using only the data available before them, it will not flag next year’s.
- Explain every alert. Each warning shows the measurements that drove it, so a technician can confirm it on the asset before work is scheduled.
Where the output goes
Alerts are only useful if they reach the people who plan work. We route them into the existing maintenance system as prioritised notifications, with the evidence attached, rather than asking planners to watch another dashboard.
Starting small
A good pilot covers one asset class with enough history, such as a fleet of pumps or a set of conveyor drives. Success criteria are agreed up front, for example how many past failures the model would have caught and how many false alerts planners will accept. Only when the pilot meets them is it worth scaling.
Sources: ISO 17359, Condition monitoring and diagnostics of machines: General guidelines (iso.org).